VLA Training Data & Annotation Company

VLA Training Data & Annotation for Physical AI

Shaip delivers VLA training data and VLA annotation — from real-world and teleoperated data collection to action-trajectory labeling, RLHF, and evaluation — so your robots and physical AI systems learn from clean, action-grounded, deployment-grade datasets.

Vla training data & annotation
Global Vetted Contributors
100 K+
Accuracy SLA
0 %+
Language Supported
10 +
In-house Global Workforce
1000 +
🔒 HIPAA Compliant
🇪🇺 GDPR Ready
✅️ ISO 27001 Certified
✅️ SOC 2 TReady
What We Deliver

VLA Training Data, built End to End

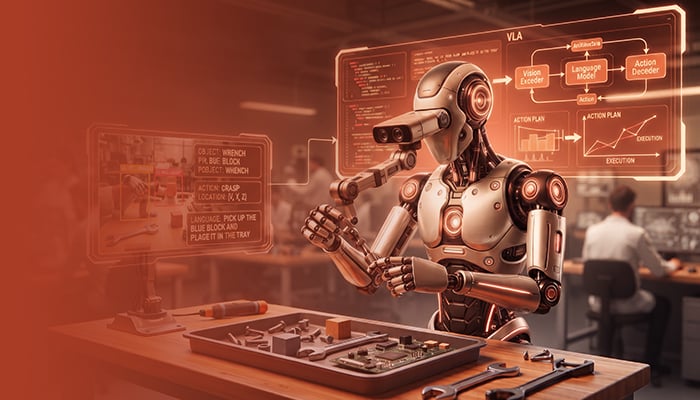
A vision-language-action model only learns when four data layers are captured and labeled in sync. Shaip delivers all four — the visual, the language, and the hard part, the action.

Visual ObservationsRGB, depth & wrist/head-camera frames
Language InstructionsNatural-language task commands
Action TrajectoriesAction tokens per degree of freedom
Outcome LabelsSuccess, failure & recovery markers
Services

VLA Annotation Services

Action is where VLA annotation gets hard. Labeling what is in a frame is table stakes; labeling what the agent did, why, and whether it worked is a different discipline. Our teams are trained specifically for action-grounded, multimodal robotics data annotation.

Action & trajectory annotation

We align action tokens to observations frame by frame — marking contact and release points, tagging language-to-action boundaries, and annotating joint states and end-effector displacement, at >95% inter-annotator agreement.

Multimodal & sensor-fusion annotation

We coordinate labeling across vision + IMU + LiDAR + audio + depth, keeping every stream time-synchronized so your model trains on coherent, fused reality — not misaligned channels.

"

Language & instruction grounding

We write, verify, and align natural-language instructions to action segments, handle multi-step and long-horizon tasks, and localize commands across 65+ languages for globally deployed robots.

Semantic, object & scene annotation

Object detection and tracking, segmentation, LiDAR annotation, point cloud annotation, 3D annotation, keypoint and pose labeling (incl. 42-keypoint skeletons), gaze, gesture, and spatial-context tags.

Outcome, intent & failure-mode labeling

Every episode is scored for success, partial completion, or failure, with intent and motion-phase tags — the signal RLHF and evaluation pipelines depend on.

Human-in-the-loop QA

Expert validation, exception handling, and multi-pass review loops keep action labels production-grade and audit-ready.

Services

VLA Training Data Collection Services

Great annotation can’t fix data you never captured. Shaip runs managed VLA training data collection so you get the exact embodiments, tasks, and edge cases your model needs.

Teleoperation & robot demonstrations

Teleoperated robot demonstrations and direct robot data collection across multiple embodiments — manipulation, pick-and-place, and long-horizon tasks as clean action-trajectory episodes.

Egocentric & human demonstration video

First-person egocentric video and human demonstration datasets — convertible to VLA format via hand-pose retargeting — to pretrain policies at a scale real-robot data alone can't reach.

Real-world, multi-environment capture

Data collected across 10+ real-world environments — kitchens, homes, streets, offices, healthcare facilities, warehouses, factories, workshops, construction sites, and roads — for true environmental diversity.

Synthetic data & augmentation

Synthetic data generation, enrichment, and taxonomy-aligned validation to fill rare, dangerous, or long-tail scenarios your fleet won't naturally produce.

Modalities we cover — all time-synchronized

RGB / mono / event cameras Depth & ToF LiDAR Radar Point cloud & 3D Sensor fusion IMU Force / torque Hand & eye tracking Audio GPS / telematics
Applications

VLA & Physical AI Use Cases

Humanoid robots

Humanoid robots

Demonstration learning and dexterous manipulation.

Robotic manipulation

Robotic manipulation

Pick-and-place, warehouse and industrial automation.

Autonomous mobility

Autonomous mobility

Perception, edge-case, and autonomous vehicle training data.

Embodied ai and world models

Embodied AI & world models

Action-grounded multimodal training for agents.

Human-robot interaction

Human-robot interaction

Gesture, gaze, and intent datasets.

Ar vr and wearable ai

AR/VR & wearable AI

Egocentric interaction and motion data.

Industrial safety

Industrial safety

PPE and unsafe-action detection in real settings.

Healthcare robotics

Healthcare robotics

Rehabilitation and clinical motion datasets.

Smart factories

Smart factories

Task automation and quality-inspection data.

Why Shaip

Why Shaip for VLA Training Data & Annotation

Shaip is an enterprise AI training data company with an integrated stack built for physical AI — not a point tool and not a crowdsourcing marketplace.

End-to-end infrastructure

From point annotation to real-world collection, synthetic data generation, RLHF-grade validation, and safety-scenario benchmarks — all under one engagement.

Multi-modal annotation depth

Vision, LiDAR, language, action, and workflow context — structured for how physical AI actually trains, evaluates, and gets to deployment.

In-person + real-world environments

Controlled studio capture and live real-world environments — both available, both managed. Custom scenarios and edge-case generation included.

Flexible global workforce

Leverage a 10,000+ in-house global workforce and 500K+ crowd-scale credentialed contributors, with real-time workforce capacity and efficiency.

Diverse, accurate & fast

Our process streamlines collection through easier task distribution and data capture directly from the app and web.

Enterprise-grade data quality

Our proprietary platform and skilled workforce use multiple quality-control methods to meet or exceed your quality standards.

Success Stories

30,000 Hours of Egocentric Video for Physical AI Training
Shaip collected authentic first-person (egocentric) video for a global technology organization to train activity-recognition, hand-object interaction, and robotics models across diverse real-world environments.
Egocentric video data collection

Problem: Acquire authentic, unstaged egocentric video at scale across diverse real-world environments.

Solution: Head-mounted mobile capture with structured onboarding and one-day QA cycles — 30,000 hours collected and 24,000+ hours annotated, up to 100 hours per participant.

Result: A deployment-grade egocentric dataset with real-world diversity across 6 activity domains and built-in consent governance.

Scaling Physical AI & Humanoid Robotics for Motion Data
Shaip built a scalable VR motion-capture pipeline delivering thousands of valid hours of egocentric data every month to train embodied AI and humanoid robots.
Physical ai

Problem: Scale from a pilot to 5,000 valid motion-capture hours per month across diverse environments and 300–400 tasks.

Solution: Five-sensor VR motion tracking with mandatory calibration across 50+ scene setups in six environment types, plus full QA.

Result: Sustainable monthly delivery of annotation-ready datasets with 1,500–2,500 participants per cycle for embodied AI and humanoid robotics.

Process

How It Works

A transparent, milestone-driven workflow designed to de-risk your project from day one.
1

Scope & taxonomy

We align on embodiments, tasks, action space, sensors, and success criteria — before a single frame is captured.

2

Collect or ingest

We run teleoperation, egocentric, and real-world capture, or ingest and structure your existing fleet data.

3

Annotate & fuse

Action, language, multimodal, and outcome labeling with synchronized, human-in-the-loop QA.

4

Validate & deliver

RLHF-grade validation, benchmark and edge-case sets, delivered in your training-ready format.

Security & Compliance

GDPR
HIPAA
ISO 9001:2015
SOC 2 Type II
ISO 27001

Build your VLA model on data you can trust

Whether you're training a humanoid, an autonomous system, or an embodied AI agent, Shaip gives you the VLA training data and annotation to get there faster — accurate, action-grounded, and enterprise-secure.

Contact Us

VLA training data is the synchronized dataset used to train vision-language-action models — pairing visual observations, natural-language instructions, action trajectories, and outcome labels into episodes a robot can learn from.

Standard annotation labels what appears in a frame. VLA annotation additionally labels what the agent did — aligning action tokens to observations, marking contact points and failure recovery, and grounding language to actions over time.

Four layers: visual observations (RGB/depth), language instructions, action trajectories mapped to the robot’s degrees of freedom, and success/failure outcome labels — ideally across many embodiments and environments for generalization.

Both. Shaip runs teleoperation, egocentric, and multi-environment VLA training data collection, and also annotates, validates, and augments data you already have.

Yes — LiDAR, point cloud, 3D, radar, IMU, depth, audio, and force/torque, all time-synchronized for sensor-fusion training.

Managed expert teams with human-in-the-loop QA and >95% inter-annotator agreement on action labels, under ISO 27001, SOC 2 Type II, and GDPR/HIPAA-ready controls.