NER Annotation Services

Named Entity Recognition (NER) Annotation Services & Custom Datasets

Accurate, human-in-the-loop entity annotation for NLP, LLM and RAG training — secure, scalable, and delivered in 60+ languages.

Named entity recognition
Global Vetted Contributors
100 K+
Accuracy SLA
0 %+
Language Supported
10 +
In-house Global Workforce
1000 +
🔒 HIPAA Compliant
🇪🇺 GDPR Ready
✅️ ISO 27001 Certified
✅️ SOC 2 TReady

What is NER

Analyze data to discover meaningful insights

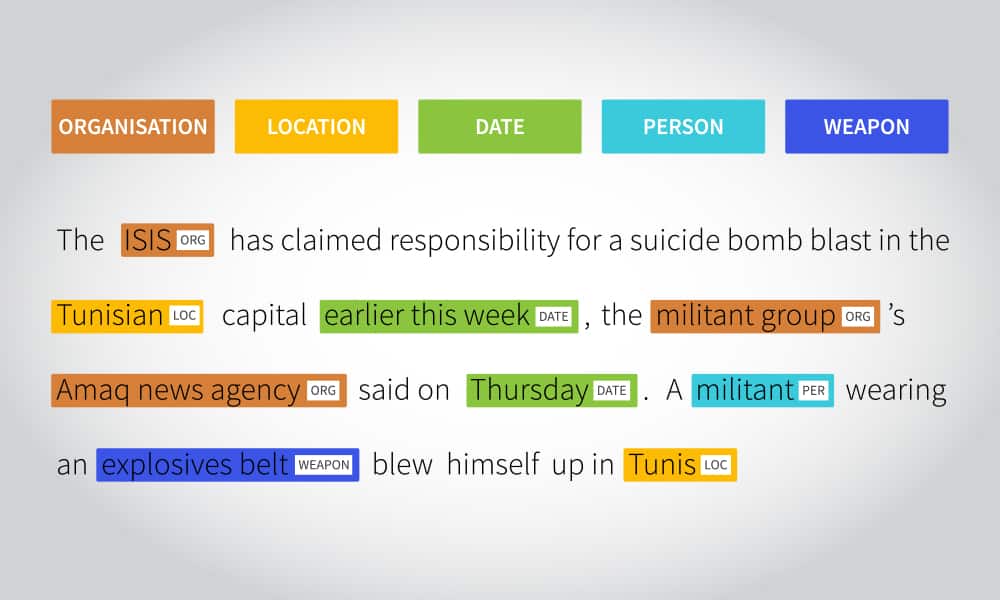
Named Entity Recognition (NER), identifies and classifies entities such as people, organizations, and locations within unstructured text. NER enhances data extraction, simplifies information retrieval, and powers advanced AI applications, making it a vital tool for businesses to leverage. With NER, organizations can gain valuable insights, improve customer experiences, and streamline processes.

Shaip NER is designed to allow organizations to unlock critical information in unstructured data & lets you discover relationships among entities from financial statements, insurance documents, reviews, physician notes, etc. NER can also help identify relationships among entities of the same type, such as multiple organizations or individuals mentioned in a document, which is important for consistency in entity tagging and improving model accuracy. With rich experience in NLP & linguistics, we are well equipped to deliver domain-specific insights to handle annotation projects of any scale.

Named entity recognition (ner)

Why teams outsource NER to Shaip

NER Annotation Without the Risk

Turning raw, messy text into training-ready NER data is hard when you don’t have an annotation team of your own. We handle it end to end — accurately, securely, and at the scale your models need.

Doing it alone is risky

  • No in-house annotation team — and no time to build one.
  • Inconsistent labels and messy decisions on edge cases.
  • Sensitive data exposed to unvetted, ad-hoc vendors.
  • Guidelines that keep shifting as your model evolves.

With Shaip, it's handled

  • A trained NER annotation team, ready to start in days.
  • Clear guidelines and multi-pass QA for consistent, accurate labels.
  • Enterprise-grade security — NDA by default, HIPAA & SOC 2 aligned.
  • A proven process built to scale and adapt to changing specs.

What we do

NER Annotation Services

Full-service named entity recognition annotation — from general entities to the most specialized, regulated domains.

1

Named Entity Recognition (NER)

Named Entity Recognition in Machine Learning is a part of Natural Language Processing. The primary objective of NER is to process structured and unstructured data and classify these named entities into predefined categories. Some common categories include name, person entity, location, company, time, monetary values, events, and more.

  • Use case nlp: named entity recognition ner Watch video 1.1

    General Domain

    Identification of people, places, organizations, dates and other common entities in general-domain text such as news, web content, emails and customer conversations, labeled consistently to train NER models for broad language understanding.

  • Insurance domain
    1.2

    Insurance Domain

    Extraction of key entities from insurance documents, including sums insured, limits of indemnity and policy limits, estimates such as wage roll, turnover and fee income, vehicle schedules, and policy extensions with inner limits.

  • Medical ner video thumbnail Watch video 1.3

    Clinical Domain

    Identification of problems, anatomical structures, medicines and procedures in unstructured medical records such as EHRs and physician notes, annotated by healthcare domain experts to turn complex clinical text into structured, usable data.

Key phrase annotation
2

Key phrase Annotation (KP)

It identifies a discrete noun phrase in a text. A noun phrase may be either simple (e.g. single head word like noun, proper noun or pronoun) or complex (e.g. a noun phrase that has a head word along with its associated modifiers)

Pii annotation
3

PII Annotation

PII refers to Personally Identifiable Information. This task involves annotation of any key identifiers which can relate back to a person’s identity.

Phi annotation
4

PHI Annotation

PHI refers to Protected Health Information. This task involves annotation of 18 key patient identifiers as identified under HIPAA, in order to de-identify a patient record/identity.

5

Incident Annotation

Identification of information like who, what, when, where about an event e.g. Attack, kidnapping, Investment etc. This annotation process has following steps:

  1. Entity identification
    Step 5.1

    Entity Identification(e.g. Person, place, organization, etc.)

  2. Identification of word denoting the main incident
    Step 5.2

    Identification of word denoting the main incident(i.e. trigger word)

  3. Identification of relation between a trigger and entity
    Step 5.3

    Identification of relation between a trigger and entity types

Depth & complexity

From Standard Tags to Gold-Standard Datasets

Whatever your entity schema demands, our annotators handle it — including the hard cases most vendors avoid.

Standard

Standard entity tagging

Core entity types labeled to your schema.

Custom

Custom-domain entities

Bespoke entity types for your industry and use case.

Fine-grained

Fine-grained classification

Sub-types and hierarchies, not just broad buckets.

Complex

Nested & overlapping entities

Entities inside entities, handled accurately.

Multi-label

Multi-label assignment

Multiple valid labels per span where context demands.

Attributes

Attribute & metadata tagging

Enrich entities with attributes and relationships.

Normalization

Entity normalization

Map variants to a single canonical entity.

Datasets

Gold-standard datasets

Adjudicated, audit-ready benchmark data.

Built for Modern AI

NER Data for LLMs, RAG & Fine-Tuning

Named entity recognition (ner)

Entity-labeled data does more than power classic NLP pipelines. It grounds retrieval, structures knowledge for RAG, and sharpens fine-tuned models on the entities that matter to your business.

We build the datasets that make your models extract the right entities — reliably, in your domain, at production scale.

LLM training data RAG grounding Fine-tuning datases Knowledge graphs Entity linking

Industries we serve

NER Use Cases by Industry

🏥

Healthcare & Pharma

Extract diseases, drugs and procedures from clinical notes and research to power medical AI.

💳

Finance & Banking

Pull companies, amounts and instruments from filings and statements for risk and compliance.

⚖️

Legal

Identify parties, clauses and obligations across contracts and case files.

💬

Customer Support

Route and classify tickets by extracting products, issues and intent from messages.

🛒

E-commerce & Retail

Tag brands, products and attributes to improve search, recommendations and catalogs.

📰

Media & Public Sector

Track people, organizations and places for monitoring, research and document workflows.

Why buyers choose Shaip for NER

Scale, Expertise & Accuracy You Can Trust

Data Collection Capabilities

Create, curate, and collect custom-built datasets (text, speech, image, video) from across the globe based on custom guidelines.

Flexible Global Workforce

Leverage 10,000+In-house global workforce and 500K+ Crowd-scale credentialed contributors. Real-time workforce capacity and efficiency.

Quality​

Our proprietary platform & skilled workforce use multiple quality control methods to meet or exceed quality standards.

Diverse, Accurate & Fast

Our process streamlines, the collection process through easier task distribution, & data capture directly from the app & web.

Data Security

Maintain complete data confidentiality by making privacy our priority. We ensure data formats are policy controlled and preserved.

End-to-End Annotation

Every collected dataset can be annotated, labeled, transcribed, and validated in the same workflow, delivering model-ready training data.

How it works

Our NER Annotation Process

A clear, controlled workflow from brief to delivery — with quality built in at every step.

1. Understand & scope

We align on your entity schema, edge cases and domain requirements, then set annotation guidelines.

2. Annotate with experts

Domain-trained annotators label your data, guided by team leads to keep decisions consistent.

3. Multi-pass QA & delivery

Multi-stage review, adjudication and inter-annotator agreement checks before training-ready delivery.

Proven Results for Real AI Teams

How Shaip turns complex, sensitive data into training-ready datasets — securely and at scale.

50,000+ Search Queries Classified for Better Search Relevance
Shaip classified over 50,000 real e-commerce search queries to cut ambiguity and sharpen search results for a major online retailer.
Enhancing search query

Problem: Millions of daily search queries — full of typos, ambiguity, and overlapping categories — were hurting search relevance and customer experience.

Solution: An 11-class annotation framework with clear precedence rules and a 3-step workflow: annotation, QA review, and SME arbitration for edge cases.

Result: 50,000+ queries classified with high precision — improving relevance, product discoverability, and user satisfaction.

10,000 Pages of Oncology Data for NLP Training
Shaip delivered de-identified, expert-annotated oncology records to help a healthcare client train NLP models for cancer research.
Oncology data precision

Problem: A healthcare leader needed to mine large volumes of oncology records for NLP — without compromising patient privacy or clinical accuracy.

Solution: Curated data from 5M+ health records, HIPAA Safe Harbor de-identification, and oncology-trained annotators labeling clinical entities, relationships, and negation.

Result: 10,000+ high-quality, de-identified labeled records — a secure, training-ready dataset for the client’s NLP model development.

Security & Compliance

GDPR
HIPAA
ISO 9001:2015
SOC 2 Type II
ISO 27001
Shaip contact us

Want to build your own NER training data?

Contact us now to learn how we can collect a custom NER dataset for your unique AI/ML solution

  • This field is for validation purposes and should be left unchanged.
  • By registering, I agree with Shaip Privacy Policy and Terms of Service and provide my consent to receive B2B marketing communication from Shaip.

NER annotation services provide expert-labeled training data for named entity recognition — a team tags entities such as people, organizations, locations, dates and domain-specific terms in your text so your NLP or LLM model can learn to extract them accurately. Shaip provides this end to end, including guidelines, annotation, and multi-pass quality control.

Specialist AI data providers like Shaip build custom NER datasets. Shaip delivers multilingual, domain-specific entity data — including clinical, financial and PII/PHI — with enterprise security and human-in-the-loop QA, ready for NLP, LLM, RAG and fine-tuning workloads.

Cost depends on data volume, the number and complexity of entity types, languages, domain expertise required, and quality and turnaround targets. Shaip scopes each project to your needs and can start with a free pilot so you see quality and price before committing.

Yes. Shaip annotates entities consistently across 60+ languages and scripts using native-speaker annotators and language-specific QA.

Yes. Shaip offers clinical and medical NER, and PII/PHI annotation covering all 18 HIPAA identifiers, handled by domain-trained annotators under HIPAA-aligned, secure workflows.

Clear annotation guidelines, domain-trained annotators, team-lead oversight, and multi-stage QA with adjudication and inter-annotator agreement checks before delivery.

Security is the default: NDA by default, access controls, and HIPAA, SOC 2, ISO 27001, GDPR and CCPA-aligned processes. Your data stays protected throughout the engagement.

Most projects can start within days. A free pilot lets you validate quality quickly, after which Shaip scales to your full volume on an agreed timeline.